Medical Visual Question Answering
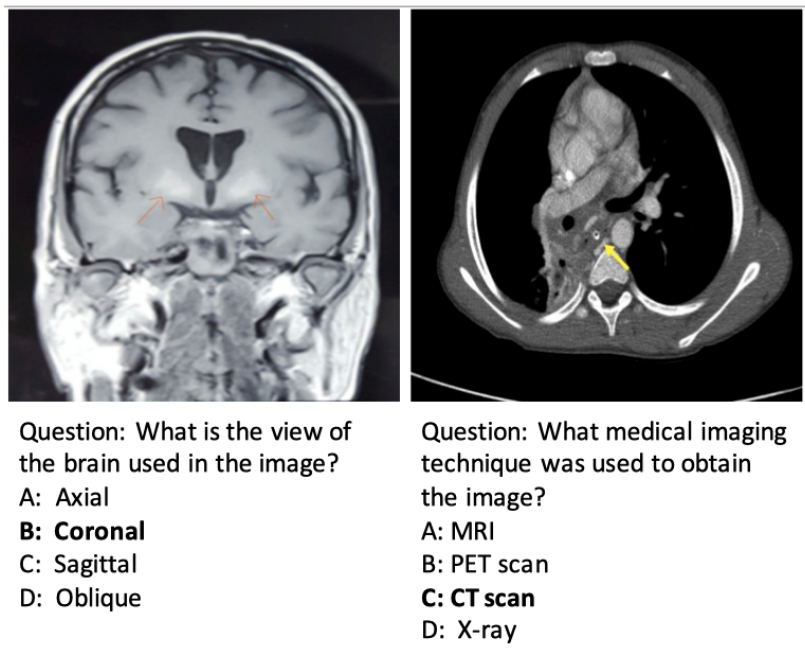
Explored the fundamentals of multimodal learning, with a focus on Vision-Language (V-L) tasks, by reviewing key papers on Visual Question Answering (VQA) and related topics. Implemented a basic VQA model using PyTorch on the Easy-VQA dataset to understand core concepts. Additionally, gained hands-on experience with Meta-AI’s MMF framework, experimenting with various VQA baselines, including state-of-the-art (SOTA) models like MMBT for radiological VQA.